
UUID v4 Explained: Format, Uses and Collision Probability
Understand the structure and purpose of UUID v4 identifiers and generate them securely inside your browser.

Modern microservices and distributed databases rely on universally unique identifiers to coordinate records globally. With UUID v4 explained in comprehensive detail, engineers can understand how 128-bit pseudorandom identifiers prevent collisions, decouple microservices from central counters, and maintain data integrity without coordination.
Unlike sequential integers, random identifiers can be minted instantly by edge servers, mobile devices, or background workers without primary key conflicts. Having UUID v4 explained clearly provides the foundation for designing resilient backend systems that scale horizontally across cloud clusters.
To generate cryptographically secure identifiers in your browser, explore EzzDo’s free UUID/GUID Generator. If ingesting structured payloads, format them using the JSON Formatter or flatten records with the JSON to CSV Converter.
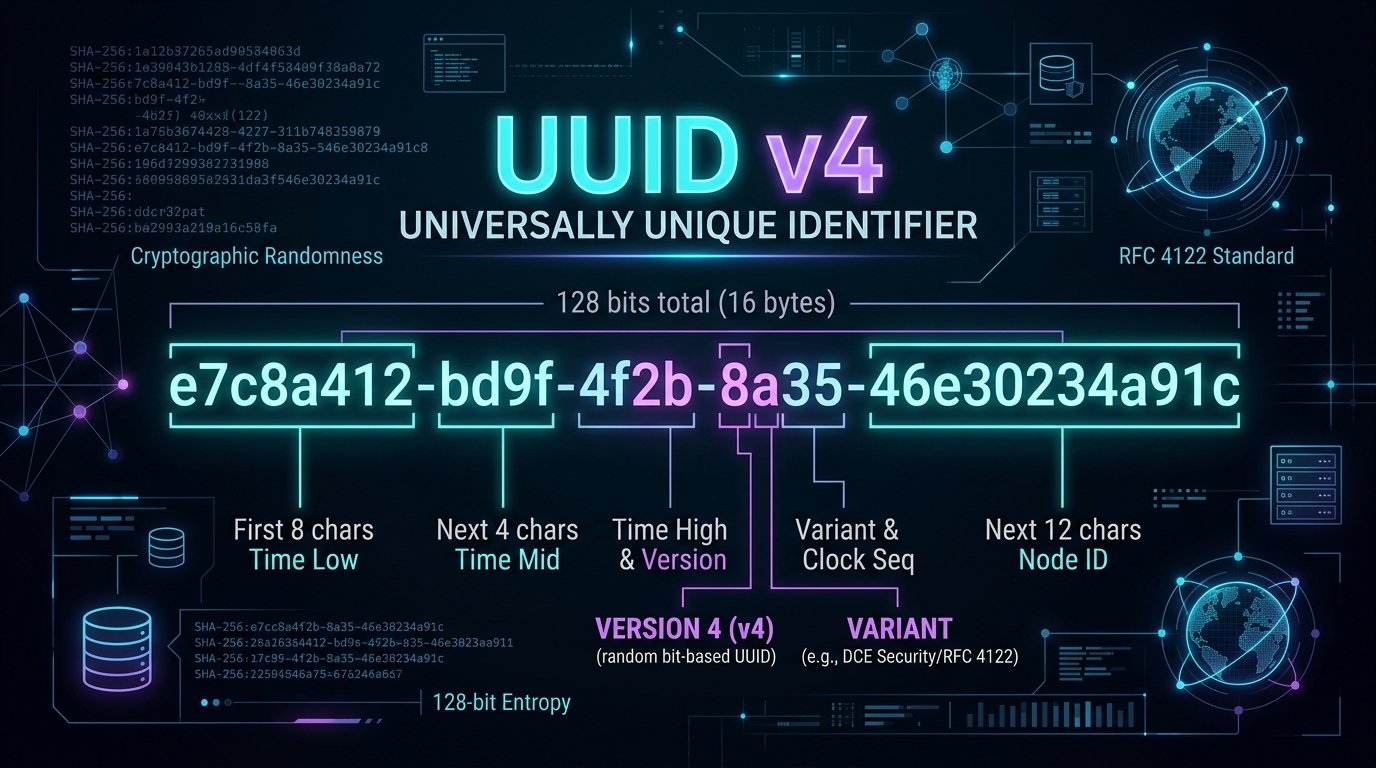
Table of Contents
UUID v4 at a Glance: Specifications and Anatomy
Review this technical specifications table summarizing the core properties of UUID v4 explained under internet standards:
| Dimension | Property | Standard | Consideration |
|---|---|---|---|
| Bit Length | 128 bits (16 bytes) | RFC 4122 / 9562 | Fits native 16-byte binary SQL columns |
| String Format | 36 characters (32 hex + 4 hyphens) | Canonical 8-4-4-4-12 | Consumes 36 bytes in ASCII columns |
| Entropy Bits | 122 pseudo-random bits | v4 bitmask | Yields 5.3 x 10^36 variations |
| Version | Digit “4” in group 3 | Bits 48-51 | Identifies random generation |
| Variant | Fixed bits 10x in group 4 | Bits 64-65 | Standard Leach-Salz layout |
| Complexity | O(1) algorithmic time | OS entropy pool | Zero network overhead or coordination |
As formalized in RFC 4122 and modernized in RFC 9562, having UUID v4 explained reinforces why version 4 remains the most ubiquitous format across modern cloud architectures.
What Does a UUID Look Like? The 8-4-4-4-12 Format
A canonical UUID is a 128-bit number displayed as thirty-two hexadecimal digits separated into five segments by hyphens:
550e8400-e29b-41d4-a716-446655440000
xxxxxxxx-xxxx-4xxx-yxxx-xxxxxxxxxxxx
|  8 hex |4 hex|4 hex|4 hex|  12 hex  |
When analyzing this structure with UUID v4 explained from an architectural standpoint, the text representation consists of five components:
- Segment 1 (8 hex / 32 bits): Lower-order pseudo-random entropy bits.
- Segment 2 (4 hex / 16 bits): Mid-order pseudo-random entropy bits.
- Segment 3 (4 hex / 16 bits): Nibble locked to
4, plus 12 random bits. - Segment 4 (4 hex / 16 bits): Variant bits (
8,9,a,b), plus 14 random bits. - Segment 5 (12 hex / 48 bits): Forty-eight random bits replacing legacy MAC addresses.
Understanding this visual grouping clarifies why UUID v4 explained represents a fundamental transition from hardware-coupled legacy identifiers to pure statistical entropy.
How Version and Variant Bits Work in UUID v4
Standard compliance reserves 6 bits for critical metadata markers. Examining this layout architecture at the binary level exposes exactly how these reserved fields operate:
UUID v4 Explained: The Version Nibble
Bits 48 through 51 define the UUID version (the first char of the third block, e.g., xxxx-4xxx). Because these four bits are always forced to binary 0100, this character will always be 4 in any valid version 4 UUID.
The Variant Nibble (Bits 64 to 67)
Bits 64 and 65 define the variant. Under RFC 4122 and RFC 9562, standard variants set these bits to binary 10. Consequently, the first character of the fourth segment must always be 8, 9, a, or b.
Subtracting 6 reserved bits from 128 total bits leaves exactly 122 bits of cryptographic entropy. With UUID v4 explained across both nibbles, developers can easily validate identifiers using simple bitmasking logic.
UUID v4 vs Other Versions (v1, v3, v5, v7)
Compare how version 4 contrasts with alternative UUID standards. Having UUID v4 explained alongside historical and modern counterparts clarifies why different algorithms exist:
| Version | Algorithm | Predictability | Index Impact | Primary Use |
|---|---|---|---|---|
| v1 | Timestamp + MAC | High (exposes MAC) | Good sequential locality | Legacy intranet systems |
| v3 | MD5 namespace hash | Deterministic | Random distribution | Deterministic namespace IDs |
| v4 | 122 random bits | Zero predictability | Page splits under write load | General distributed IDs, APIs |
| v5 | SHA-1 namespace hash | Deterministic | Random distribution | Deterministic entity mappings |
| v7 | Unix ms timestamp + random | Time-ordered | Excellent clustering | Modern database primary keys |
While UUID v7 provides temporal sorting advantages for database indexing, UUID v4 explained demonstrates why version 4 remains the universal standard for tokens, trace IDs, distributed events, and APIs where leaking timestamp information is undesirable.
Common Enterprise and Distributed System Use Cases
Organizations deploy version 4 identifiers across diverse architectures. Having UUID v4 explained in production contexts demonstrates how decoupled architectures eliminate database bottlenecks:
- Microservice Primary Keys: Services generate records independently across regions without central ID coordination.
- Offline Mobile Apps: Devices generate entities locally and sync seamlessly once connected.
- API Correlation IDs: Tracking transactions across services requires a unique identifier (e.g.,
X-Request-ID). - Queue Message IDs: Task runners like Celery and Kafka assign UUID v4 identifiers to each job for idempotency.
- Session Tokens: Carts and upload sessions utilize UUIDs as transient references before registration.
- Object Storage Keys: S3 stores use random UUID prefixes to balance partition traffic.
Studying how UUID v4 explained solves these challenges allows engineering teams to build resilient distributed backends that scale horizontally without communication overhead.
UUIDs vs Sequential Auto-Increment Database IDs
The choice between sequential numeric keys (such as SQL BIGINT AUTO_INCREMENT) and random UUIDs is a critical architectural decision. Having UUID v4 explained across both paradigms reveals crucial trade-offs:
Advantages of Sequential Numeric IDs
- Compact Storage: An 8-byte
BIGINTrequires half the storage of binary UUIDs and one-quarter of string UUIDs. - Optimal Clustering: New rows append strictly to index page ends, preventing page fragmentation.
- Readability: Numbers like customer
#1042are simpler to communicate verbally.
Vulnerabilities of Sequential Numeric IDs
- Business Intelligence Leakage: Competitors infer sales velocity by observing order increments.
- IDOR Security Risks: Attackers seeing profile URL
/users/501scrape/users/502if authorization fails. - Multi-Master Collisions: Independent databases allocating sequential integers produce duplicate IDs.
When evaluated with UUID v4 explained systematically, random identifiers eliminate enumeration vulnerabilities and multi-region write contention while trading off index compactness.
Can Two UUID v4 Values Collide? The Math Behind 122 Bits
One of the most persistent inquiries developers encounter is whether two independently generated version 4 UUIDs can ever be identical. With UUID v4 explained mathematically, we evaluate the precise statistical mechanics of the Birthday Problem.
Because 6 bits are reserved for standard markers, a version 4 UUID possesses 122 bits of variable entropy. The total number of distinct possible identifiers is:
2^122 ≈ 5.317 x 10^36 possible identifiersIn probability theory, the probability p of encountering a duplicate among n values from keyspace N = 2^122 is calculated via p(n) ≈ 1 - exp(-n^2 / (2 * N)):
- Generating 1 Billion UUIDs: Collision probability is approximately
9.4 x 10^-20. - Generating 1 Trillion UUIDs: At one trillion identifiers, collision probability is only
9.4 x 10^-14. - 50% Collision Threshold: Requires generating
2.71 x 10^18UUIDs. Minting one billion UUIDs per second continuously takes over 85 years of nonstop generation to reach a 50% collision likelihood.
Therefore, having UUID v4 explained with mathematical rigor proves that for all practical engineering purposes, collisions with a cryptographically sound random generator are virtually impossible.
Database Indexing Traps: B-Tree Fragmentation and Storage
While version 4 collision probability is practically zero, using random UUIDs as clustered primary keys introduces performance hurdles. Having UUID v4 explained in the context of database internal engines highlights critical storage best practices:
The Phenomenon of B-Tree Page Splits
Relational databases store table data clustered by primary key in B+ Tree structures. Because version 4 identifiers are entirely random, each inserted row lands in an arbitrary position within the index tree:
- Page Splits: When an index leaf page fills up, inserting a random key forces the engine to split the page into two half-empty pages.
- I/O Thrashing: As the table exceeds RAM buffer capacity, random inserts trigger disk I/O to swap cold index pages into memory.
- Index Bloat: Repeated page splits result in leaf pages that are only 50% to 70% full, inflating storage overhead.
Storage Format Optimization: 16 Bytes vs 36 Bytes
Storing UUIDs as text strings (VARCHAR(36)) requires 36 bytes per row, plus string comparison overhead. In contrast, storing raw binary (BINARY(16)) or using PostgreSQL’s native UUID type consumes only 16 bytes, cutting memory requirements by more than 55%.
For high write throughput, modern teams combine UUID v4 explained concepts with time-ordered alternatives like UUID v7 for clustered keys while retaining version 4 for public API references.
UUIDs Are Not Secrets: Security and Access Control Rules
A widespread anti-pattern is assuming that an entity is secure simply because its URL contains a seemingly unguessable UUID. Having UUID v4 explained from a cybersecurity perspective exposes why identifier obscurity must never substitute for cryptographic authorization:
The Myth of “Unguessable” Public URLs
Engineers often create endpoints like /invoice/a1b2c3d4-e5f6-4a7b-8c9d-0e1f2a3b4c5d and omit authentication, reasoning no attacker could guess it. This fails because URLs are logged in browser histories, web server logs, corporate proxies, and leaked via HTTP Referer headers.
Pseudo-Random Number Generator (PRNG) Vulnerabilities
A version 4 UUID is only as strong as its random generator. If a developer uses a weak generator (such as Math.random()), an attacker observing generated identifiers can reconstruct seed state and predict past and future UUIDs.
Always verify that your libraries invoke a CSPRNG, such as crypto.getRandomValues(). When UUID v4 explained is coupled with strict server authentication, role-based access control, and rate limiting, your applications remain secure.
UUID v4 Explained: 7 Best Ways to Generate Identifiers
To ensure high performance, security, and reliability when producing identifiers, adhere to these seven industry best practices for UUID v4 explained:
- 1. Always Use Cryptographic Entropy: Never rely on basic random functions. Leverage operating system entropy pools (such as
crypto.randomUUID()or Python’suuid.uuid4()) to guarantee unguessable randomness. - 2. Validate Incoming Strings Strictly: Use standardized regex (
^[0-9a-fA-F]{8}-[0-9a-fA-F]{4}-4[0-9a-fA-F]{3}-[89abAB][0-9a-fA-F]{3}-[0-9a-fA-F]{12}$) to reject malformed payloads. - 3. Enforce Unique Constraints: Always place a
UNIQUEconstraint or primary key definition on UUID database columns. - 4. Store as 16-Byte Binary Values: Reduce memory consumption and index bloat by packing canonical string UUIDs into native
UUIDorBINARY(16)columns. - 5. Preserve Lowercase Formatting: Standardizing on lowercase hexadecimal characters avoids comparison mismatches in caching layers like Redis.
- 6. Protect Endpoints with Authorization: Never treat a UUID as an access token. Always authenticate requests using verified JWTs or session cookies.
- 7. Leverage Browser Generation: When preparing mock datasets, use EzzDo’s free UUID/GUID Generator for fast, private batch creation.
Production Code Examples: Node.js, Python, Go, and SQL
Integrating version 4 identifiers into production applications is straightforward. Here is UUID v4 explained with production-grade syntax for modern software stacks:
Node.js and Browser JavaScript (Native Web Crypto)
import { randomUUID } from 'node:crypto';

// Generate a cryptographically secure UUID v4
const newId = randomUUID();
console.log('UUID v4:', newId);

// Validate version 4 format with regex
const isValid = /^[0-9a-f]{8}-[0-9a-f]{4}-4[0-9a-f]{3}-[89ab][0-9a-f]{3}-[0-9a-f]{12}$/i.test(newId);
console.log('Valid:', isValid); // true
Python Standard Library (uuid Module)
import uuid

user_id = uuid.uuid4()
print("UUID:", str(user_id))
print("Version:", user_id.version)  # 4

# Raw 16-byte binary for database storage
binary_bytes = user_id.bytes
print("Bytes:", len(binary_bytes))  # 16
Go (google/uuid Package)
package main

import (
    "fmt"
    "github.com/google/uuid"
)

func main() {
    id := uuid.New()
    fmt.Printf("UUID v4: %s (v%d)
", id.String(), id.Version())
}
SQL and PostgreSQL Native Generation
-- PostgreSQL native UUID table
CREATE TABLE customer_orders (
    order_id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    customer_email VARCHAR(255) NOT NULL,
    total_amount NUMERIC(10, 2) NOT NULL
);
Having UUID v4 explained with native code samples allows developers to deploy robust identifier generation across their technical stack immediately.
Common Mistakes When Implementing UUID v4 Identifiers
Even seasoned backend developers make subtle implementation mistakes with version 4 identifiers. With UUID v4 explained for system reliability, review these common pitfalls to keep production performant:
- Non-Cryptographic Randomness: Using pseudo-random generators seeded by time makes IDs predictable and subject to collision.
- Index Fragmentation: Using random UUIDs as clustered keys on high-insert tables causes severe B-Tree page thrashing. Consider UUID v7 instead.
- Storing Strings in Databases: Storing 36-byte strings instead of native 16-byte binary types balloons table and index sizes.
- Stripping Hyphens Inconsistently: Removing hyphens creates confusion when integrating with APIs expecting canonical formatting.
- Treating UUIDs as Capability Tokens: Relying on unguessable URLs without validating session permissions leaves endpoints vulnerable.
- Case Sensitivity Mismatches: Storing uppercase strings in Redis while searching for lowercase causes cache misses unless normalized.
Awareness of these pitfalls ensures that having UUID v4 explained translates directly into resilient, high-speed software architecture.
Frequently Asked Questions
Find answers to common technical questions regarding how UUID v4 explained applies to real-world development:
Reviewing these answers with UUID v4 explained resolves common doubts regarding formatting, uniqueness guarantees, and production database storage.
UUID v4 Architecture and Implementation Checklist
Verify each item on this technical checklist for UUID v4 explained before production deployment:
- Entropy Pool: Verify servers have active, non-blocking entropy sources available.
- Format Standardization: Standardize on 36-character canonical lowercase strings for network payloads.
- Column Type: Choose native
UUIDorBINARY(16)columns for database tables. - Regex Validation: Enforce UUID regex validation on all user-supplied query parameters.
- Constraint Definition: Place
UNIQUEconstraints on database identifier columns. - Access Control: Confirm protected endpoints enforce session authentication rather than identifier obscurity.
- Tool Verification: Use EzzDo’s free UUID/GUID Generator for instant test data generation.
Mastering Distributed Identifiers with UUID v4
Universally unique identifiers represent an elegant architectural solution in distributed computing. Having UUID v4 explained thoroughly illustrates how 122 bits of cryptographic randomness liberate modern software from sequential bottlenecks, single-point-of-failure database auto-increments, and multi-region replication conflicts.
By pairing cryptographically secure entropy pools with sound database indexing strategies and strict server authorization, developers can build globally scalable, collision-free backends with absolute confidence. Enhance your developer workflow today with EzzDo’s client-side suite: create instant keys with our UUID/GUID Generator, validate schemas with the JSON Formatter, and convert tabular datasets using our JSON to CSV Converter to power your next engineering breakthrough with UUID v4 explained. Key qualities: engineering, reliability, infrastructure, optimization.